Promise 的并发控制源码解析

前言

Promise 的并发控制源码解析,一看就是老面试题了

正文

一般我们讲到 Promise 的并发控制,很多时候我们都是和 HTTP 请求结合起来的

因为浏览器是有连接数量限制的,过多的 HTTP 请求会先挂起,等待先前发送的请求完毕之后再发送挂起的请求

每个请求都需要占用额外的内存,过多的 HTTP 请求挂起还可能导致浏览器崩溃

所以,合理的发送速度就显得格外的重要

这次,我们来品一品 async-pool 这个库的源代码,它的源代码,非常的简洁,如下

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
async function* asyncPool(concurrency, iterable, iteratorFn) {
const executing = new Set()
// 消费其中一个 Promise ,并从 executing 中删除该完成的 Promise
async function consume() {
const [promise, value] = await Promise.race(executing)
executing.delete(promise)
return value
}
for (const item of iterable) {
const promise = (async () => await iteratorFn(item, iterable))().then((value) => [
promise,
value,
])
executing.add(promise)
if (executing.size >= concurrency) {
yield await consume()
}
}
while (executing.size) {
yield await consume()
}
}

module.exports = asyncPool

这里面核心的地方有三个,其一个是 Promise.race 这个 api

其二是 for 循环中的根据 executing.size >= concurrency 判断来 consume 掉已完成的 Promise

其三是如果“池子中” Promise 没有达到上限,则需要依次 consume ,此时和限流就无关了

Promise.race 下,如果某个 Promise 已完成或失败,那么返回的 Promise 就会对应的完成或者失败

对应到代理里面的 consume 函数,即每次我们都从 executing 中取一个已完成 Promise ,然后把该 Promise 从 executing 中删除,这样下一次调用 consume 就会继续

在 for 循环中,我们可以发现对传入的 Promise, 对其返回的结果也进行了包装

1
2
3
4
for (const item of iterable) {
const promise = (async () => await iteratorFn(item, iterable))().then((value) => [promise, value])
// ...
}

这里是为了记住当前的 Promise 对象,这样在 consume 函数中,我们就能删除这个把这个已完成的 Promise 从 executing 中删除

对于最后的 while 循环,当“池子”中的 Promise 数量已经小于我们指定的数量时,那么可以明确 for 内部的 yield await consume() 就不会执行到

但是剩下的 Promise 我们又不能不去 consume 进而获取结果(因为这个 asyncPool 这个函数是要获取结果返回的)

所以最后我们需要把“池子”里的 Promise 都 consume 掉,这样传入的所有 Promise 都能正确的被返回

当然,这里使用的是比较新的语法,比如 async/await 关键字,以及生成器函数

回到使用上,官方给了我们一个小例子,如下
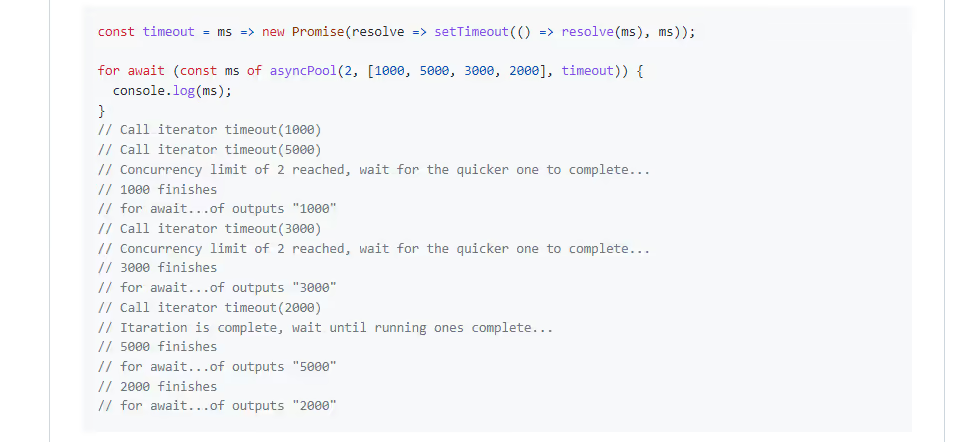
可以发现,它的传参是根据参数不同来生成不同的 Promise 的,但实际上,生成的 Promise 并不是这么简单的

更多的时候,我们需要更加灵活的参数,比如下面的调用

1
2
3
4
5
6
myAsyncPool(
// 指定最大并发个数
3,
// 每个异步的工厂函数
[() => axios.get('/abc'), () => axios.delete('/a')],
)

为了达成上面的效果,我们可以对源代码进行简单地修改,修改后如下

这里用了点 ts 泛型,整体大框架和源码保持不变

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
export async function* asyncPool<T>(concurrency: number, iterable: Iterable<() => Promise<T>>) {
type WrapperPromise = Promise<[WrapperPromise, T]>
const executing = new Set<WrapperPromise>()
async function consume() {
const [promise, value] = await Promise.race(executing)
executing.delete(promise)
return value
}
for (const item of iterable) {
const promise = item().then((val) => [promise, val]) as WrapperPromise
executing.add(promise)
if (executing.size >= concurrency) {
yield await consume()
}
}
while (executing.size) {
yield await consume()
}
}

看起来很不错,不过这还是不够灵活,比如我们无法一次性的传入所有的异步工厂函数

即我们需要分离创建“池子”和往“池子”放异步函数这两个操作,所以我们可以按照核心逻辑写出下面的代码

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
export class AsyncPool<T> {
private concurrency: number
private running: Set<Promise<T>>
private waiting: Array<() => Promise<T>>

constructor(concurrency: number, iterable: Iterable<() => Promise<T>>) {
this.concurrency = concurrency
this.running = new Set()
this.waiting = []
for (const item of iterable) {
this.add(item)
}
}

add(promise: () => Promise<T>) {
if (this.running.size < this.concurrency) {
const p = promise().then((val) => {
this.running.delete(p)
while (this.running.size < this.concurrency && this.waiting.length > 0) {
const waitPromiseFactory = this.waiting.shift()!
this.add(waitPromiseFactory)
}
return val
})
this.running.add(p)
} else {
this.waiting.push(promise)
}
}
}

这里我们使用两个池子来表示,一个是正在执行的“池子”,一个是等待中的“池子”

每次我们添加一个 Promise 时,如果此时正在执行的“池子”还有位置,那么直接放入执行即可

如果此时正在执行的池子没位置了,我们就先放入等待池子中

当正在执行的“池子”中某一个 Promise 执行完毕之后,我们需要删除执行“池子”中对应的 Promise

然后我们需要判断,如果此时等待“池子”中有未处理的 Promise ,那么就可以加入执行“池子”中开始执行

和上面版本对比的话,缺点就是没法使用 for await 了,适合零散的 Promise 的并发控制